Garbled characters in DBF: finding the right encoding
A DBF file has no flag that says “this is UTF-8”. The code page is either named by a single header byte or not named at all — and then it has to be worked out from the content. That is how “Café” turns into “Caf╔” or “CafÚ”.
Where the problem comes from
DBF is a single-byte format: every character takes exactly one byte. Which letter a byte stands for depends on the code page. The letter “é” is stored as 0x82 in DOS code page 437, but as 0xE9 in windows-1252. Read it with the wrong table and you get a different character:
| Byte | cp437 (DOS, US) | cp850 (DOS, Western Europe) | windows-1252 |
|---|---|---|---|
0x82 | é | é | ‚ |
0xE9 | Θ | Ú | é |
0x84 | ä | ä | „ |
0xFC | ⁿ | ¸ | ü |
The program that wrote the file knew its own table. The program that reads it has to take the table from the header — or guess.
The language driver: byte 29 of the header
Byte 29 of a DBF header (counting from zero) holds the Language Driver ID, a code that names the code page. The values you will meet most often:
| Code | Encoding | Typical origin |
|---|---|---|
0x01 | cp437 | DOS programs in the US, early dBase and FoxPro |
0x02 | cp850 | DOS programs in Western Europe |
0x03, 0x57 | windows-1252 | Windows programs, Visual FoxPro |
0x64, 0x1F | cp852 | DOS programs in Central Europe |
0xC8 | windows-1250 | Windows programs in Central Europe |
0x26, 0x65 / 0xC9 | cp866 / windows-1251 | Cyrillic DOS / Windows programs |
0x7B, 0x7A, 0x78, 0x79 | Shift-JIS, GBK, Big5, EUC-KR | Japanese, Chinese and Korean systems (multi-byte) |
0x00 | not specified | about half of the files in the wild |
The byte can also be wrong: a file was created by one program, extended by another, and the header kept its original value. It is a strong hint, not a guarantee.
Reading the symptoms
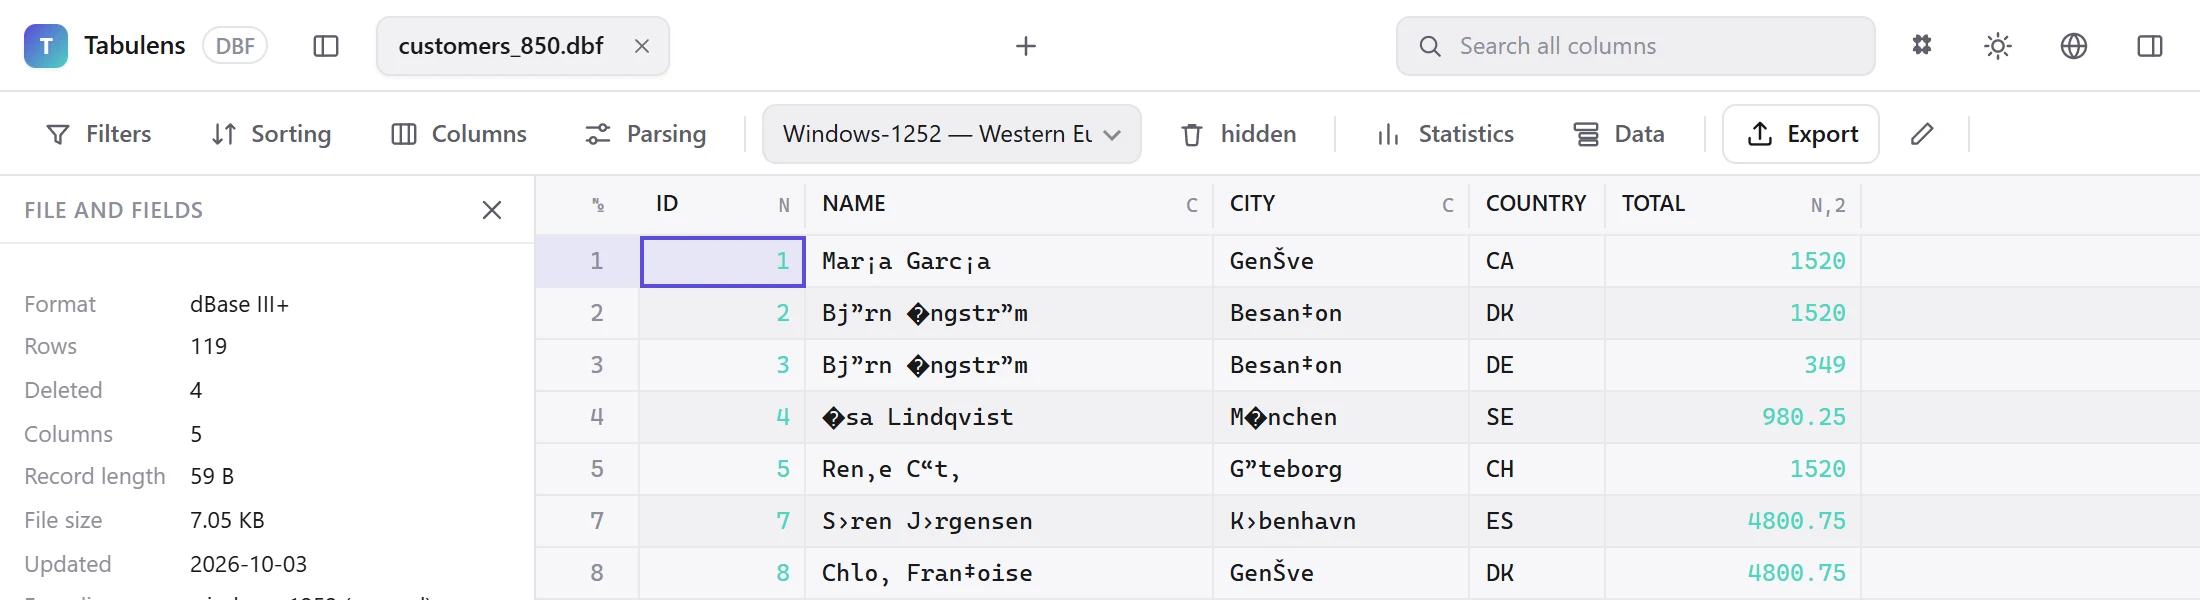
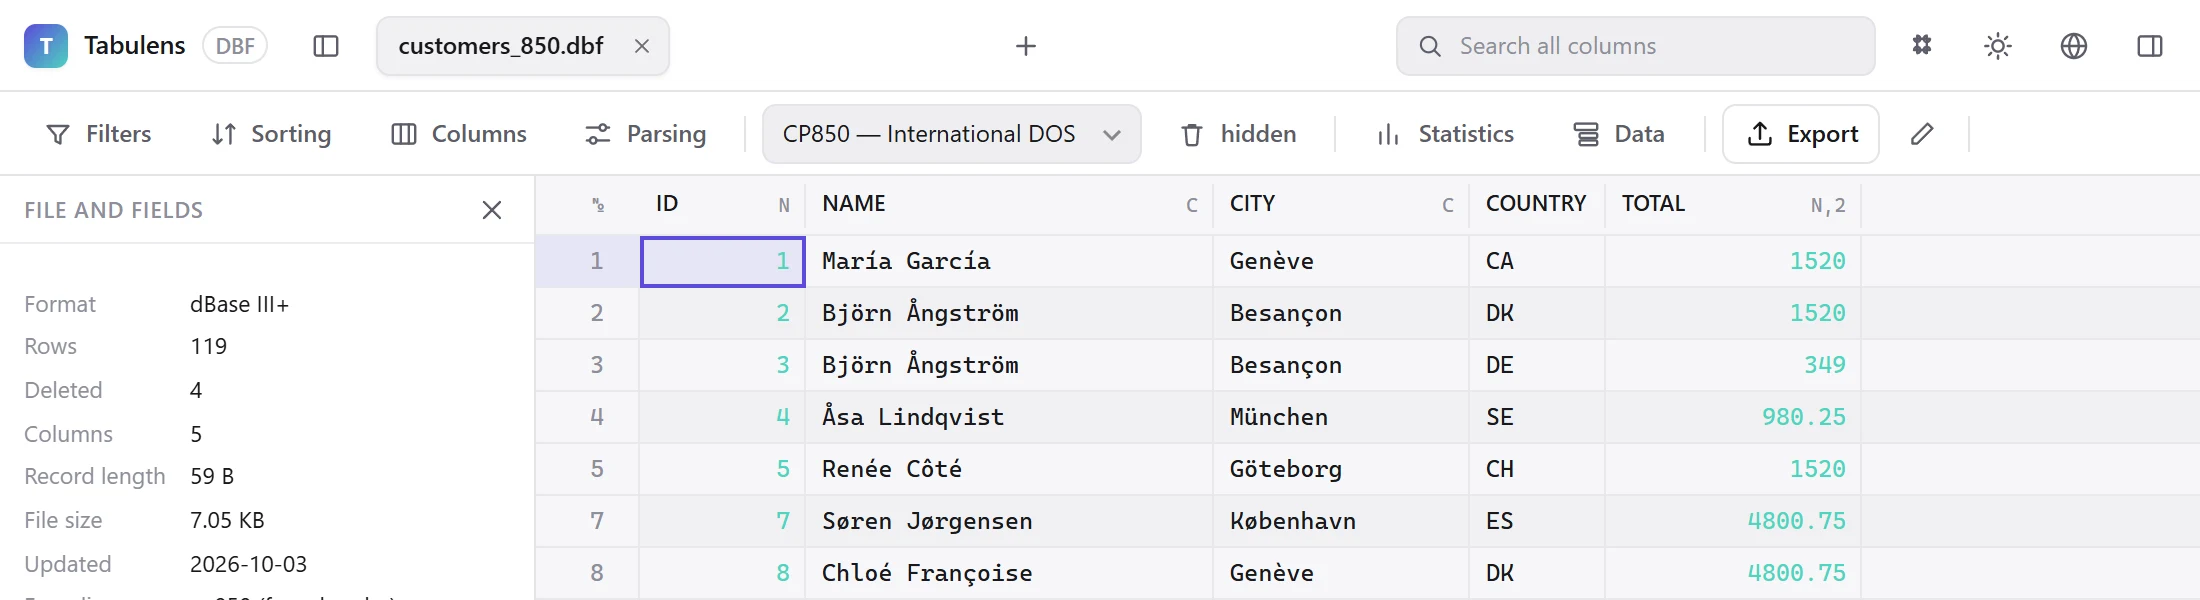
The pattern of the garbage tells you what happened:
- Box-drawing characters inside words (
╔ ║ ╗ ╚ ╣): the file was written in a Windows code page and is being read as a DOS one. The upper half of DOS tables is full of line-drawing characters, and accented letters land there. - “‚”, “ƒ”, “„” where é, â, ä should be: the opposite — DOS data read as windows-1252.
- “Θ”, “Ú”, “Φ” in place of é: windows-1252 data read as cp437 or cp850.
- “é”, “ü”, “ä”: two bytes per letter — the text is UTF-8 and is being read as a single-byte table. Rare in DBF, but modern tools do write it.
- Replacement characters (�): the decoder met bytes that do not exist in the table, or truncated multi-byte text.
For Central European text (Polish, Czech, Hungarian), the equivalent confusion is cp852 versus windows-1250; for Cyrillic it is cp866 versus windows-1251.
What to do in practice
- Open the file and look at the text fields. If they read correctly, the encoding was picked up from the header or detected from the content.
- If they do not, switch the encoding in the toolbar and try the likely candidates: cp437 and cp850 for files from DOS-era programs, windows-1252 for Windows ones.
- Switching does not reopen the file. Only the byte-to-character table changes, and nothing in the file is touched unless you save your edits.
- If some fields read correctly and others do not, the file probably mixes data from several sources. That can only be fixed by whoever produced it.
One more subtlety: field names are text too, and are decoded with the same table. If the column headers are garbled but the data is fine, the two were written in different encodings.
Why not just convert to UTF-8
The temptation is understandable, but DBF cannot hold it: field length is given in bytes, and accented letters take two bytes each in UTF-8. A C(20) field fits twenty plain Latin letters but fewer accented ones — anything beyond the limit is silently cut off.
So when data is exported back to DBF, the encoding is always single-byte, and field lengths are recalculated from the real data in the target encoding. To get UTF-8 text out of a DBF, export to CSV, JSON or XLSX instead.
FAQ
Can I find the encoding without opening the file?
Look at byte 29 of the header in a hex editor. Bear in mind that it is often zero or wrong — the content is more reliable.
Why does one program read the file correctly and another does not?
When the language driver is missing, programs fall back differently: one uses the Windows system code page, another assumes a DOS one. The file is the same.
Will switching the encoding in a viewer change the file?
No. It only changes how bytes are displayed. The file stays as it is until you explicitly save changes.
Free for personal use. Your file is not uploaded to a server. Windows version — 3.5 MB, no installation: details. Organizations: license.