How to open a Parquet file
Parquet is a columnar format that Spark, pandas, DuckDB, BI tools and cloud warehouses export to. Looking inside usually takes Python or a special utility. Here a .parquet file opens by drag and drop, like any table.
What you get
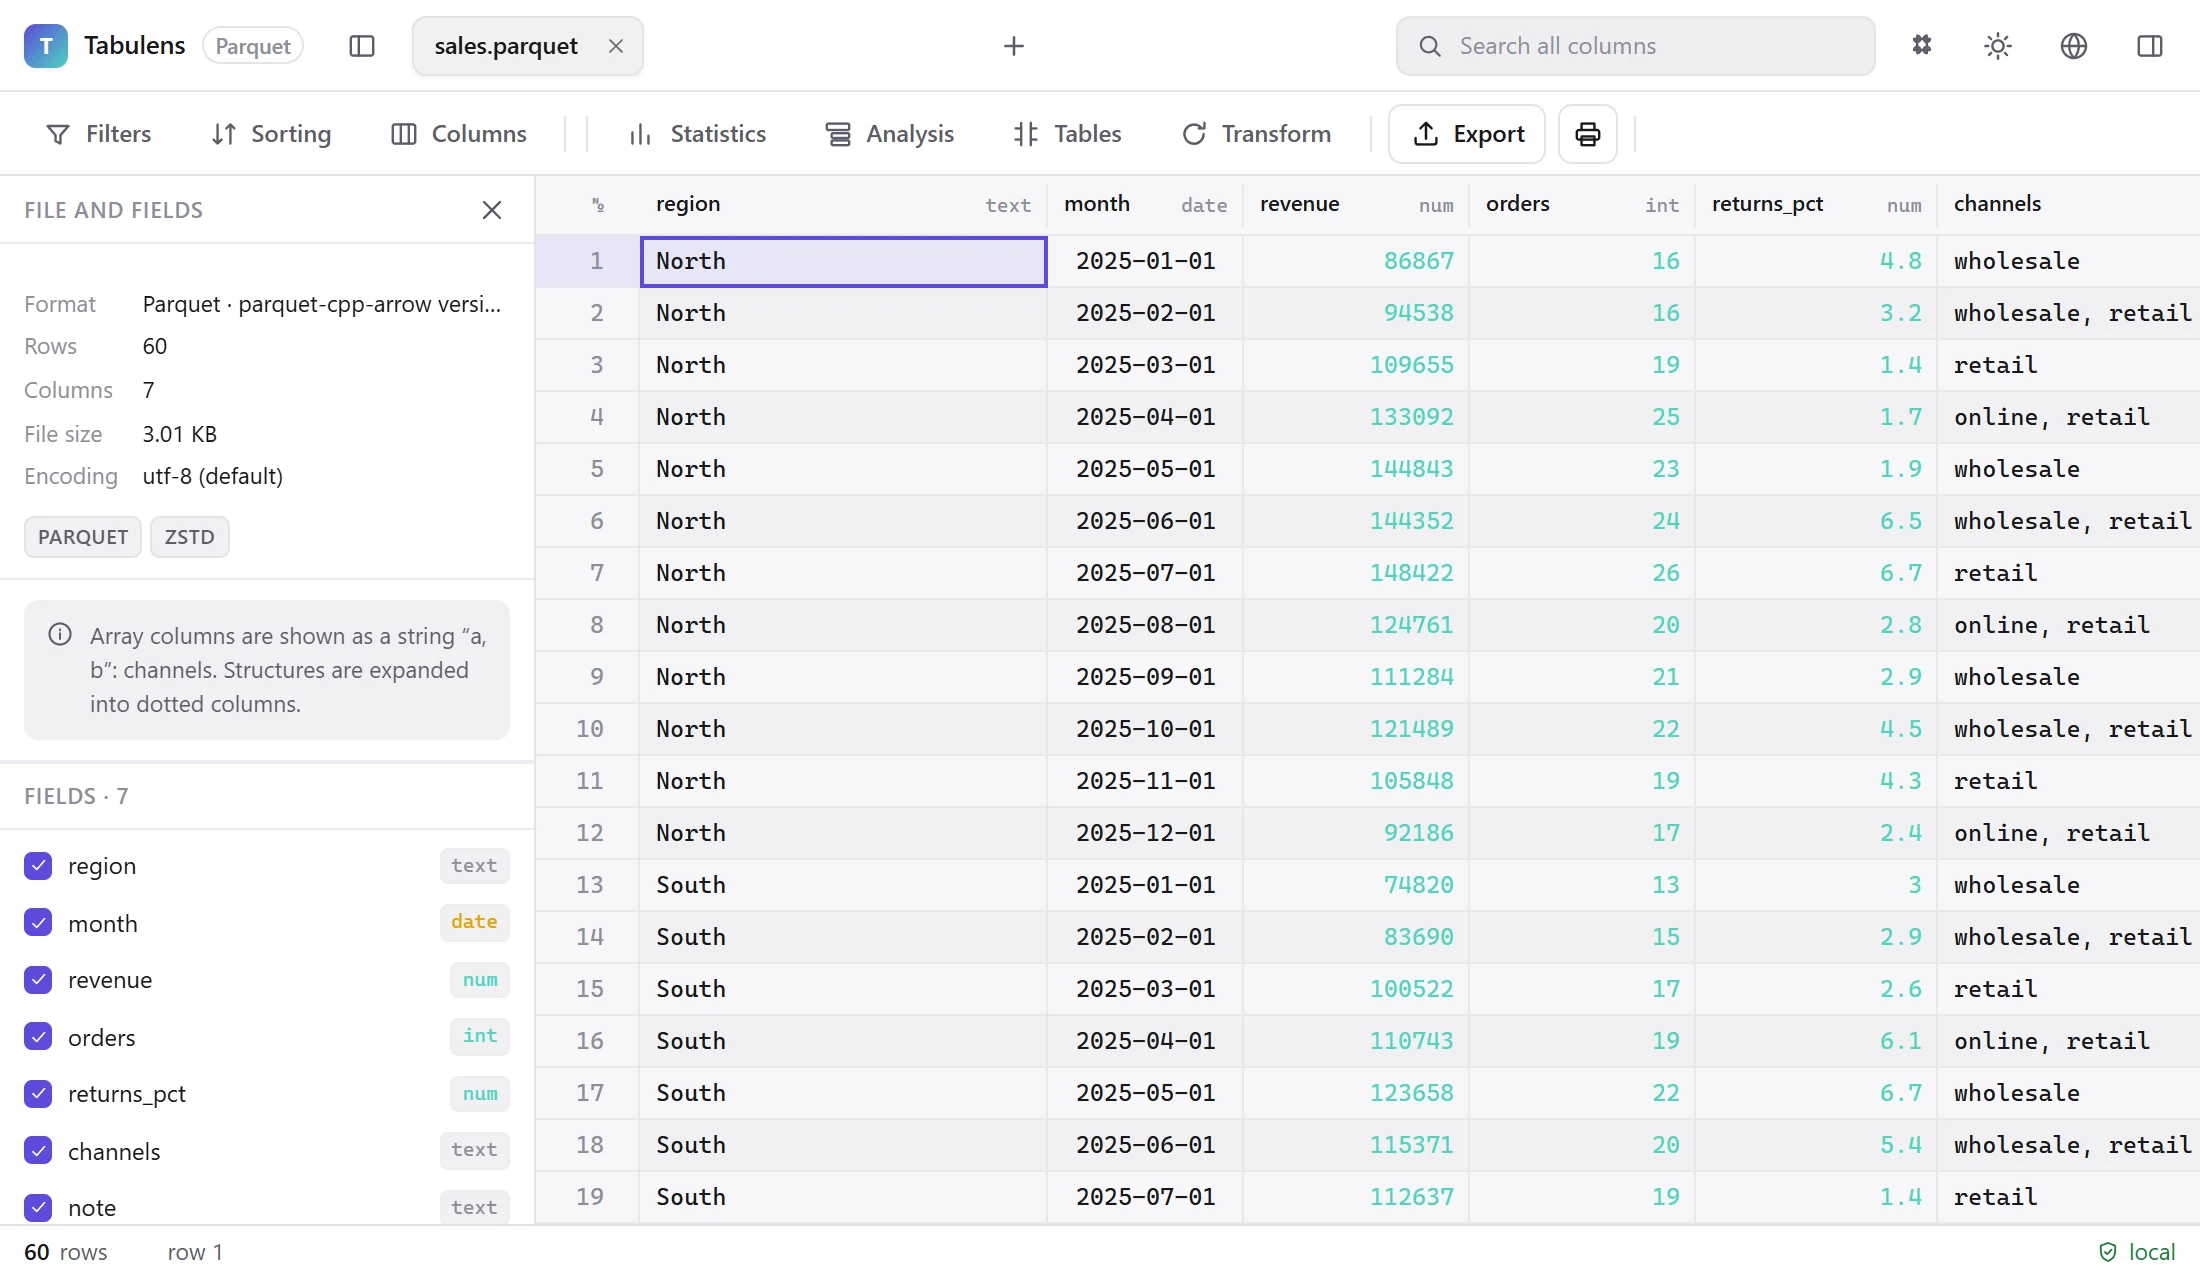
A table with the same abilities as the other formats: filters, sorting, search, statistics, pivot tables, charts, export to Excel, CSV, JSON and more. The side panel shows the row and column counts, the writer version and the compression.
What is supported
- Compression: Snappy, Gzip, LZ4, Zstandard and none.
- Encodings: plain, dictionary, RLE and delta — the ones Arrow, Spark and DuckDB write.
- Types: integers and floats, strings, date and time, decimals, booleans.
- Nested: lists are shown as a string “a, b”, structs are flattened into columns with dots.
Columns are read on demand: a large file opens fast, and work happens on the columns you see.
Parquet opens for viewing only: edits cannot be written back to this format — export the table to CSV or Excel. Brotli, LZO and encrypted files are not read yet.
FAQ
Do I need Python or Spark?
No. The file is read in your browser tab; nothing has to be installed.
Does the file go to a server?
No. Parsing is local, and the page technically cannot send the file’s contents to any other address.
Can I save changes to Parquet?
No, viewing only. Export the result to CSV, Excel, JSON and other formats.
How do I convert Parquet to CSV or Excel?
Open the file and press “Export”: pick a format and save. From the console the same is done by Tabulens.exe convert file.parquet --to csv.
Free for personal use. Your file is not uploaded to a server. Windows version — 3.7 MB, no installation: details. Organizations: license.